Memory metric unavailable — current capacity retained
No usable memory readings were found, so memory was held at what you have now. The saving is real; it just never came from shrinking memory. Installing the CloudWatch agent unlocks more.
 MAXOPS ADVENTURES
‹ All issues
How MaxOps decides an instance is too big — the formula, the statistic, the three tiers, and every single reason it refuses to recommend a change.
You're paying for the box. Your workload is the glowing bit inside it. Rightsizing is just measuring the gap — carefully enough that you'd bet production on the answer.
Every recommendation in this issue answers one question: is there a cheaper instance that still comfortably fits this workload? "Comfortably" is doing a lot of work in that sentence, and the next sixteen pages are about exactly how much.
Can't you just look at CPU and pick something smaller?
That's how you get paged at 3am. Average CPU hides every spike, vCPU counts lie across generations, and a missing metric is not the same as a zero. All three have an answer here.
capacity you need =

  capacity you have now
  ×  the share you actually use
  ÷  the share you want to use
1000 × 35% ÷ 70% = 500

the cheapest instance scoring 500
or more -- with enough memory too
Read it right to left. You're using 35% of a box worth 1000. I want you at 70% of the new one. So you need 500. That's the entire idea.
Memory runs the identical calculation with its own headroom setting, also 70% by default. A candidate has to satisfy both before it is considered at all.
Same number. Different chips, different generations, different real throughput.
What MaxOps compares insteadNow "is this target actually big enough?" has an honest answer across families, generations and architectures.
Four vCPUs is four vCPUs, surely?
Not remotely. A vCPU is a billing unit, not a performance one. Two instances with the same count can differ by a wide margin in real throughput — different silicon, different clock, different generation, sometimes a different architecture entirely.
If sizing counted vCPUs, every cross-generation and cross-architecture recommendation would be a guess. Scoring each instance type with a benchmark makes "big enough" a comparison between two numbers on the same scale, which is what lets the rightsizer suggest a newer family or a Graviton target at all.
It also means the answer degrades honestly: when a type has no CoreMark score in the catalog, it isn't guessed at — the candidate simply can't be evaluated.
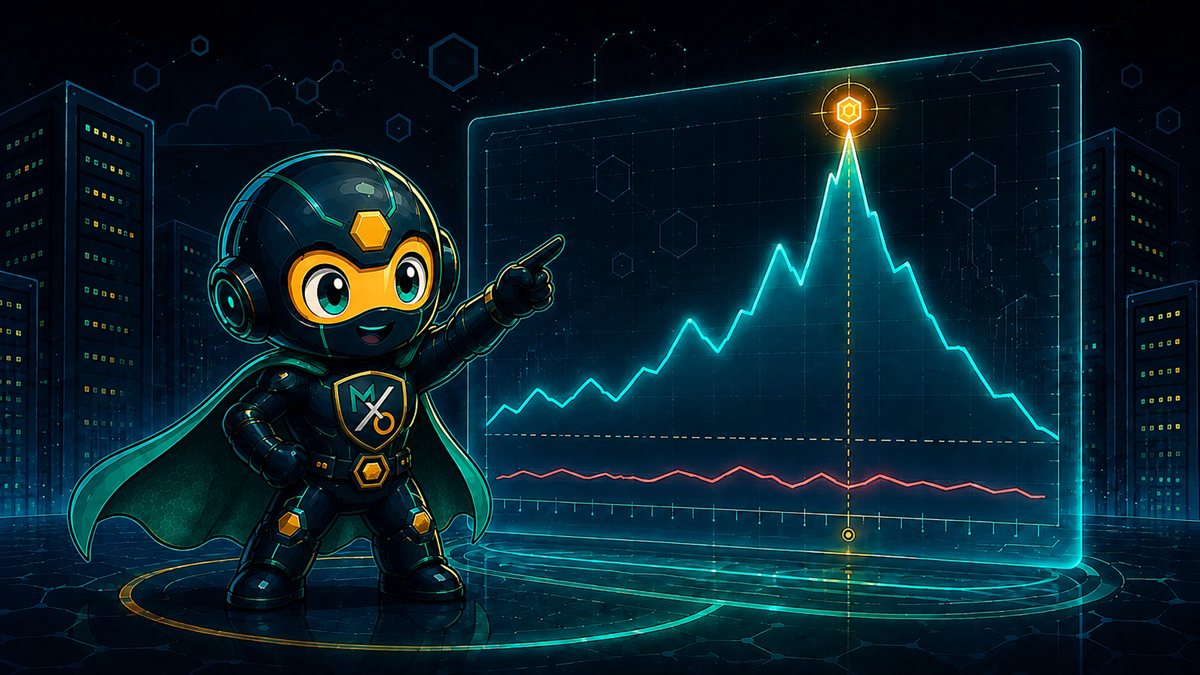
An instance averaging 8% CPU that hits 95% every weeknight at close of business is not an 8% instance. Shrink it on the average and you break the only hour that mattered.
An unmeasured dimension is treated as fully used, so it can never be reduced.
What the recommendation tells youIf I have no measurement for something, I assume you need every bit of what you already have. I will never hand back capacity I couldn't watch you using.
This is the capacity floor, and it's why a missing metric doesn't have to block a recommendation outright. The common case: CPU is always available from CloudWatch, memory usually isn't. Rather than refuse everything, the rightsizer sizes CPU on evidence and pins memory at the current instance's memory — so the target may be cheaper, but never smaller in the dimension nobody could measure.
The recommendation says so on its face — "memory metric unavailable, current capacity retained" — so you always know which parts of the advice rest on measurement and which rest on caution.
A "free memory" series would invert the entire recommendation.
If several could matchThe standard CloudWatch agent metric wins. Anything else is a fallback, and a candidate carrying no usable readings is passed over for the next one.
Why is memory so much harder than CPU?
Because AWS can't see inside your instance. CPU comes free from the hypervisor; memory only exists if you installed the CloudWatch agent — and you got to name the metric whatever you liked.
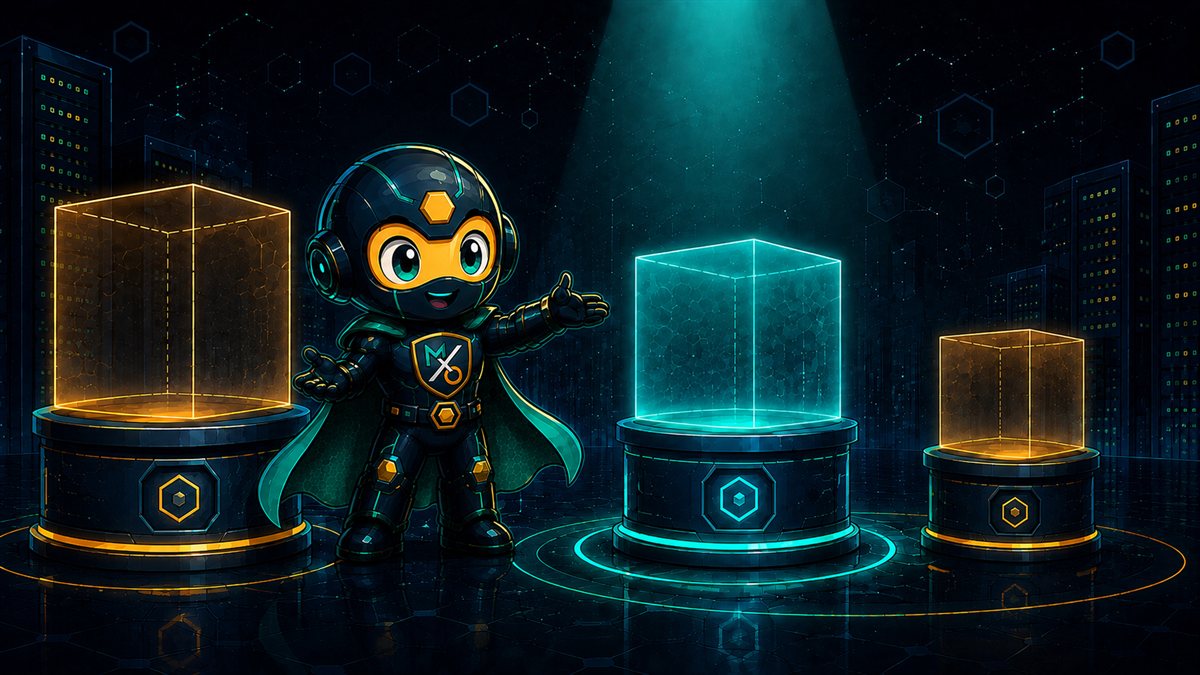
The same workload, run through the formula three times with three ratios. A ratio of 0.55 says "size it so we'd sit at 55% — plenty of room to grow." 0.85 says "run it hot, take the money." Same evidence, three appetites for risk.
Note which direction is which: the lower the ratio, the bigger the instance I'll ask for. Conservative costs you more and sleeps better.
Tiering is a selection layer, not a re-run — candidates are generated once, then sorted into tiers. Balanced is the headline pick, and the rules enforce that the balanced ratio always matches your headroom setting, so the tier list can never disagree with the headline recommendation.
ElastiCache uses the identical three ratios. The vocabulary is deliberately shared.
Everything measured, everything low-risk. Safe to act on.
Plausible, but something needs a human. Most real recommendations land here.
Real money, but requires migration work — Graviton, architecture changes.
A hard incompatibility. Not shown as a saving.
Out of scope for this pass — e.g. managed by an ASG or ECS.
A tool that only says "yes" or "no" has to lie in one direction. Five verdicts let me say "this is real money but it needs your judgement" without either hiding it or pretending it's safe.
The distinction that matters most: CONDITIONAL is not a weak ACTIONABLE. It means the compute maths passed and something about network, storage, or capability evidence needs a human who knows the workload. Treating those as equivalent is how rightsizing tools lose trust.
So most of my recommendations will be CONDITIONAL?
Probably — and that's the design, not a defect. The next page shows exactly how strict the bar for ACTIONABLE is.
Classification reads four columns. Nothing else. Not the savings, not how much you'd like it to be actionable.
| Network & storage limits | Network risk | Storage risk | Warnings | Verdict |
|---|---|---|---|---|
| Something would break | any | any | any | Rejected |
| Fine, but something unknown | any | any | any | Conditional |
| All clear | Low | Low | none | Actionable |
| All clear | Medium or High | any | any | Conditional |
| All clear | any | Medium or High | any | Conditional |
Read the third row carefully: Actionable needs everything low and nothing unknown. A single medium risk on either network or storage is enough to drop a recommendation to Conditional. That is a deliberate choice — confidence ahead of coverage — and a setting rather than a law of nature.
Note what is absent: the other risks you'll meet on page 12 don't appear here at all. They're shown to you, but they never change the verdict — a missing measurement doesn't need to block anything, because page 6's rule already guarantees it can't shrink what it couldn't see.
Anyone can find a cheaper instance. The work is knowing when not to. A hard restriction isn't a warning — the candidate is thrown out entirely.
If five of them don't affect the verdict, why compute them at all?
Because you're the one clicking the button. A HIGH memory risk won't stop me recommending — but you deserve to see it before you act, and so does whoever reviews the change afterwards.
Alongside the seven areas, every recommendation lists exactly what was observed and why the verdict landed where it did. That's what makes a recommendation reviewable months later, rather than a number you have to take on faith.
A single Graviton recommendation can legitimately carry high migration effort, medium network risk and high storage risk all at once — and still be worth showing you, as an Opportunity.
"This target uses the arm64 (Graviton) architecture. Realizing this saving requires validating and migrating the application to arm64 (rebuilt binaries/images and compatible dependencies). Compatibility is not validated by this recommendation."
Graviton targets are often the biggest number on the page. They are also a port, not a resize. I will never file that under "safe to act on" and let you find out later.
Benchmark scoring is what makes Arm targets comparable in the first place — the upside of measuring real throughput rather than counting vCPUs. But compute capacity is the only thing it establishes. Whether your binaries, base images and dependencies build and run on arm64 is not validated, and the recommendation says so in plain language rather than burying it in a risk score.
The same treatment applies to any target with less memory than the current instance while memory is unmeasured — you get the candidate, clearly flagged, with a note that enabling memory metrics is what would turn it into a real recommendation.
Headline series is daily Maximum — an honest ceiling that survives CloudWatch rollup. Daily Average must never be the headline.
Fetched on demand when you open the detail view; never stored per scan.
The trend exists so you can overrule me. It never gates a decision — it's the evidence you need to accept or reject what I said.
Why is network missing from the long view?
Because I'd have to lie to show it. NetworkIn and NetworkOut are byte counters. Past CloudWatch's 63-day fine retention, a daily maximum gets computed from one-hour sums — which smears a sharp burst into a gentle mound and understates your true peak.
So network peak evidence stops at the 60-day decision window, and the long trend simply omits it. An honest long-range network peak is not recoverable, so it isn't drawn. Memory often has far less than 15 months too, and the chart tells you how many days it actually has rather than padding the line out. A short memory history is expected, not a fault.
A saving landing exactly on either figure counts as clearing it.
Below either line it is not shown at all.
Two floors. It has to beat a cent, and it has to beat whatever minimum you set. Below either, it isn't a recommendation — it's noise with a price tag.
The boundary is handled exactly rather than approximately. Money arithmetic done the ordinary way can put a saving of precisely one cent on either side of the line depending on rounding luck — so the comparison is made in a way that always falls the same way for the same numbers, and hitting the threshold exactly counts as meeting it.
Why keep the old float for what's displayed?
So the figures on your screen don't shift underneath you between releases. The exact comparison decides whether a recommendation appears; the amount you read is unchanged.
Every recommendation arrives with the target, the tier alternatives, the verdict, the seven risk dimensions, the reason codes, and 15 months of evidence behind it. Not a number — a case you can review, defend, or reject.
And if you disagree with me, the trend is right there to prove me wrong. That's the deal.
Everything you just read — percentile evidence, target ratios, tiers, a verdict with disclosed risk — is the house pattern. Only the measurements change.
0.55 / 0.70 / 0.85 tier ratios, plus a split between engine CPU and host CPU — a cache node can be busy in one and idle in the other — and its own memory target ratio.Each has its own issue coming. The rack shows what's in production.
Every recommendation carries short notes explaining what was observed. These are the ones you will see most often.
No usable memory readings were found, so memory was held at what you have now. The saving is real; it just never came from shrinking memory. Installing the CloudWatch agent unlocks more.
The smaller machine can't carry the peak that was measured. Not a warning — that option was discarded.
You are hitting storage limits today. Shrinking is off the table until that's resolved — and it may mean this instance needs to grow, not shrink.
Only one side of a read/write pair was recorded at some moments. What was seen is kept as a floor, not treated as the whole story.
AWS doesn't publish a firm sustained figure for the target, or quotes only an "up to" burst number. Capacity is therefore approximate, which caps the verdict at Conditional.
Some network counters weren't available. Noted for your information — this one alone will not downgrade a recommendation.
An Arm/Graviton target. Always an Opportunity, never "safe to act on" — your application has to be rebuilt and validated, and that is not checked for you.
Something else owns this instance's lifecycle, so it is set aside here and handled as part of its group instead.
A capability might be in use and couldn't be confirmed. Unknown counts against the change, so the recommendation is held back rather than pushed through.
The rightsizer's best feature is its restraint — the capacity floor, the conservative maximum across three windows, and a bar for ACTIONABLE that most recommendations deliberately fail to clear.